Your own AI server,
on your own premises
Turn-key GPU servers built on NVIDIA's newest RTX PRO Blackwell generation. Designed, installed and supported by Microark engineers in Malaysia, so you can run private LLMs, train models and keep your data under your own roof.
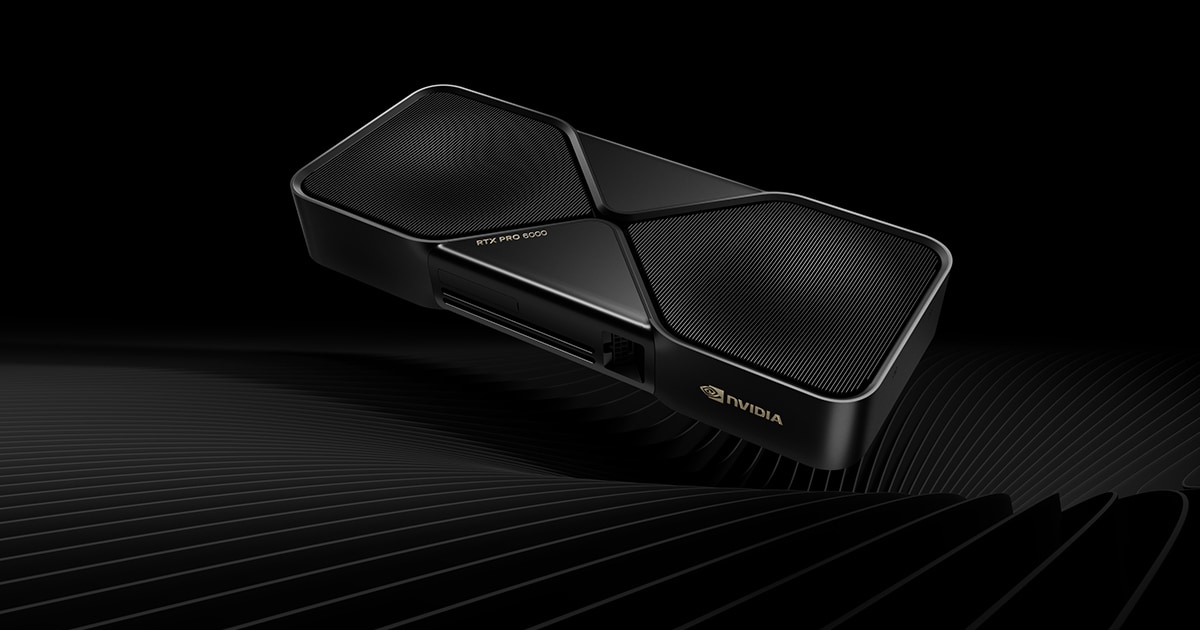
Server Packages
Basic, Mid-Range and Advanced
Every package is a complete, turn-key server. Pick the GPU memory your work needs; we handle the rest.
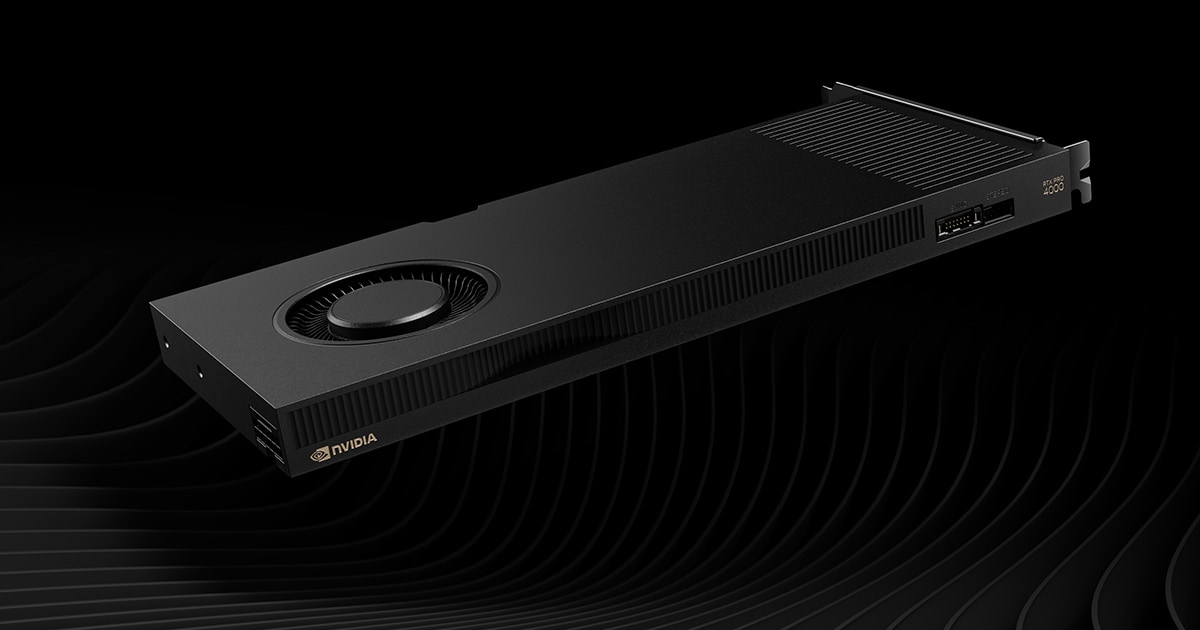
NVIDIA RTX PRO 4000 Blackwell
A private AI server for one team, lab or classroom
- Private AI assistant for your staff
- LLMs up to ~30B parameters (quantised)
- Computer vision and image generation
- Teaching labs and student projects
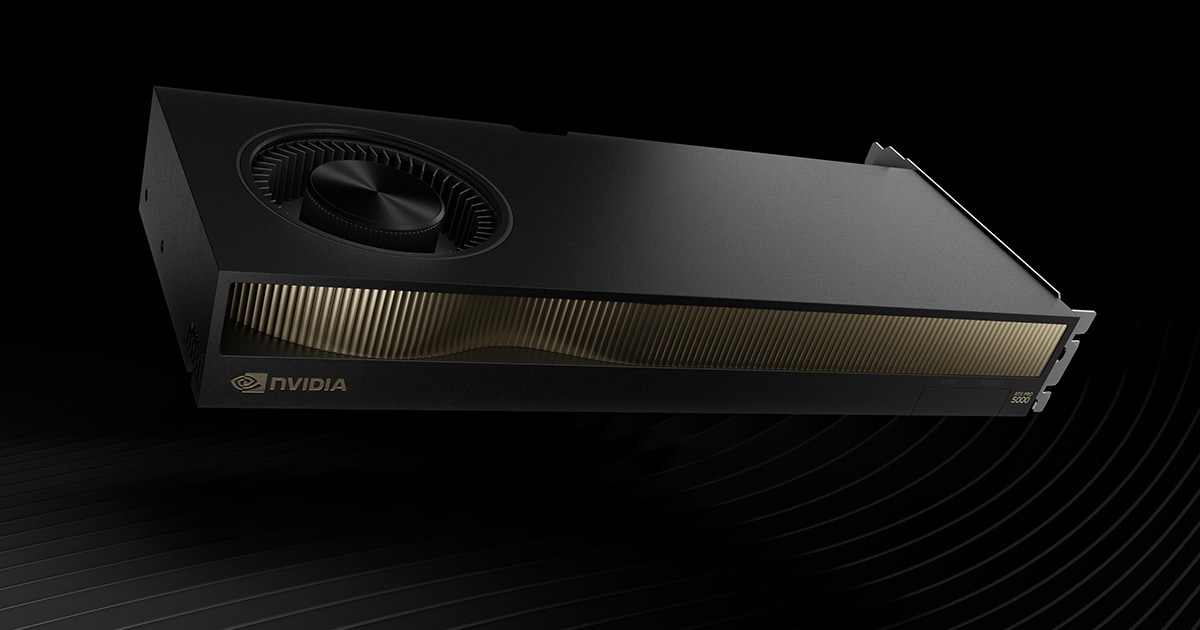
NVIDIA RTX PRO 5000 Blackwell
Serious AI work: 70B models, medical imaging and fine-tuning
- 70B LLM inference (FP4 / FP8)
- Medical imaging and 3D segmentation
- LoRA and QLoRA fine-tuning
- 2 users at once with GPU partitioning
NVIDIA RTX PRO 6000 Blackwell
Flagship research and shared multi-user compute
- 70B LLM fine-tuning with full batches
- Up to 4 isolated GPU instances (MIG)
- Genomics, protein and molecular AI
- Rental-ready: earn from idle hours
Prices in MYR, excluding support plans and SST where applicable. Final pricing depends on GPU availability and is confirmed in a written quotation.
NVIDIA, RTX and Blackwell are trademarks of NVIDIA Corporation. Product images courtesy of NVIDIA.
Every Server Includes
Turn-key, from box to first model
NVIDIA RTX PRO Blackwell GPU
The newest professional generation, with ECC memory, 5th-gen Tensor Cores and FP4 support.
Fast, expandable platform
64 GB DDR5 (expandable to 128 GB) and a 4 TB NVMe drive. Mid-Range and Advanced add a 16 TB backup drive.
AI stack, ready on day one
Ubuntu Server 24.04, CUDA 12+, Docker, PyTorch, vLLM and Ollama installed and burn-in tested.
Delivered and installed
Our engineers deliver, install and hand over the server at your premises anywhere in Malaysia.
Local warranty handling
We handle warranty claims with Malaysian distributors, so you never chase paperwork.
Human engineer support
Real engineers on call, with support plans from 1 to 3 years, up to 24×7.
Who It's For
Built for teams that need AI on their own terms
Train models without queueing for shared clusters. We prepare grant-ready spec sheets and quotations.
Patient scans and genomic data never leave your building. PDPA-friendly by design.
Run a private LLM on your company documents, with no per-token API bills and no data sent to third parties.
A private AI assistant for teachers, and real GPUs for Computer Science, robotics and media students.
Generative video, 3D and Unreal Engine rendering on hardware you own.
A fixed cost instead of monthly cloud bills. Your models and IP stay in-house.
Optional Managed Rental
Buy it as an asset. Rent out the idle hours.
Most GPUs sit idle at night, on weekends and between projects. With our managed rental service, your team always books first, and spare hours are rented to vetted researchers and companies. The income goes back to you.
Base case for the Advanced server: 35% own use, half of the remaining hours rented at RM 7 per GPU-hour, after a 15% platform fee and electricity. Actual results vary with usage and demand.
A scheduler gives your own projects priority, always.
We find renters, handle billing and keep workloads isolated.
About 4-year payback in our base case for the Advanced server.
Own your compute vs rent from the cloud
The same GPU hours, very different outcomes
Support Plans
Kept running by real engineers
| Plan | Coverage | What's Included | Price |
|---|---|---|---|
Silver 1 year | Mon–Fri, 9am–6pm · 4-hour remote response | Next-business-day parts, 2 maintenance visits a year, OS updates | RM 5,850 / year |
Gold 3 years · Recommended | Priority escalation · 2-hour response | Advance parts replacement, 6 maintenance visits, CUDA and driver upgrades | RM 14,950 |
Platinum 3 years · 24×7 | 24×7 · 1-hour critical response | Engineer on site within 4 hours if the server is down, standby spare parts, dedicated account manager | RM 24,050 |
Frequently asked questions
How long does delivery take?+
Typically 2–5 weeks after the purchase order, depending on NVIDIA GPU allocation. We confirm the lead time in your quotation.
What do the prices include?+
The complete turn-key server: GPU, platform, storage, AI software stack, burn-in testing, delivery and installation. Prices are in MYR and exclude support plans and SST where applicable. Final pricing is confirmed in a written quotation.
Can you build a custom configuration?+
Yes. We build multi-GPU, rack-mount and larger memory or storage configurations on request. Tell us your workload and we will size it.
Do you help with grant applications and procurement?+
Yes. We prepare spec sheets and quotations you can attach to grant applications, tenders and internal budget requests.
Can we rent out the server when we are not using it?+
Yes. With our optional managed rental service, your team books first and idle hours are rented to vetted researchers and companies, with the income going back to you.
Not sure which server fits your work?
Tell us what you want to run. Our engineers will size the right server and send a written quotation.